Architecting Scalable Next.js Applications on Vercel and AWS

Most articles about Next.js at scale read like documentation with a byline attached. So instead of writing another one, we sat down with someone who lives with these decisions every day. Marcus Reyes has spent the last several years as a Solutions Architect and Cloud Architect. He moves mid to large sized companies off legacy frontends and onto Next.js, usually running Vercel and AWS together rather than picking one over the other.
What follows is a 12 question conversation, lightly edited for length. We asked the questions we hear most often from engineering leaders who are past the “let’s try Next.js” stage and into the “how do we not regret this in two years” stage.
1. Let’s start simple. What does “enterprise architecture” actually mean when we’re talking about a frontend framework?
Marcus: People hear enterprise and think it means bigger servers or a fancier org chart. It’s really about predictability. Picture 12 teams shipping to the same Next.js codebase, or a platform that touches finance, healthcare, or retail at real volume. The architecture has to answer questions nobody asks on a side project. Who owns this route? What happens when a dependency breaks at 2am? How do we roll back a bad deploy without waking up the whole company?
Enterprise architecture is the set of decisions that keeps growth from turning into chaos. For Next.js, that means being deliberate about rendering strategy, deployment boundaries, and how the frontend talks to everything behind it. You don’t want whoever touched the code last making those calls by accident.
The human side of it
I’d also add that enterprise architecture has a human component people underestimate. One developer can hold a small project’s framework decisions entirely in their head. Once 12 teams depend on those same decisions, they become a shared contract. Documentation matters more. Naming conventions matter more. An inconsistent pattern multiplies its cost with every team that copies it.
So a lot of what I do isn’t glamorous. I write down the rules everyone agreed to, then build guardrails so people don’t have to remember them from memory.
2. Why pair Vercel and AWS at all? Wouldn’t it be simpler to pick one?
Marcus: Simpler on paper, yes. But most companies I work with already run a substantial AWS footprint before Next.js even enters the picture. Their databases, internal services, compliance tooling, and existing IAM setup all live there. Ripping that out to go all in on one vendor isn’t realistic, and honestly it isn’t smart.
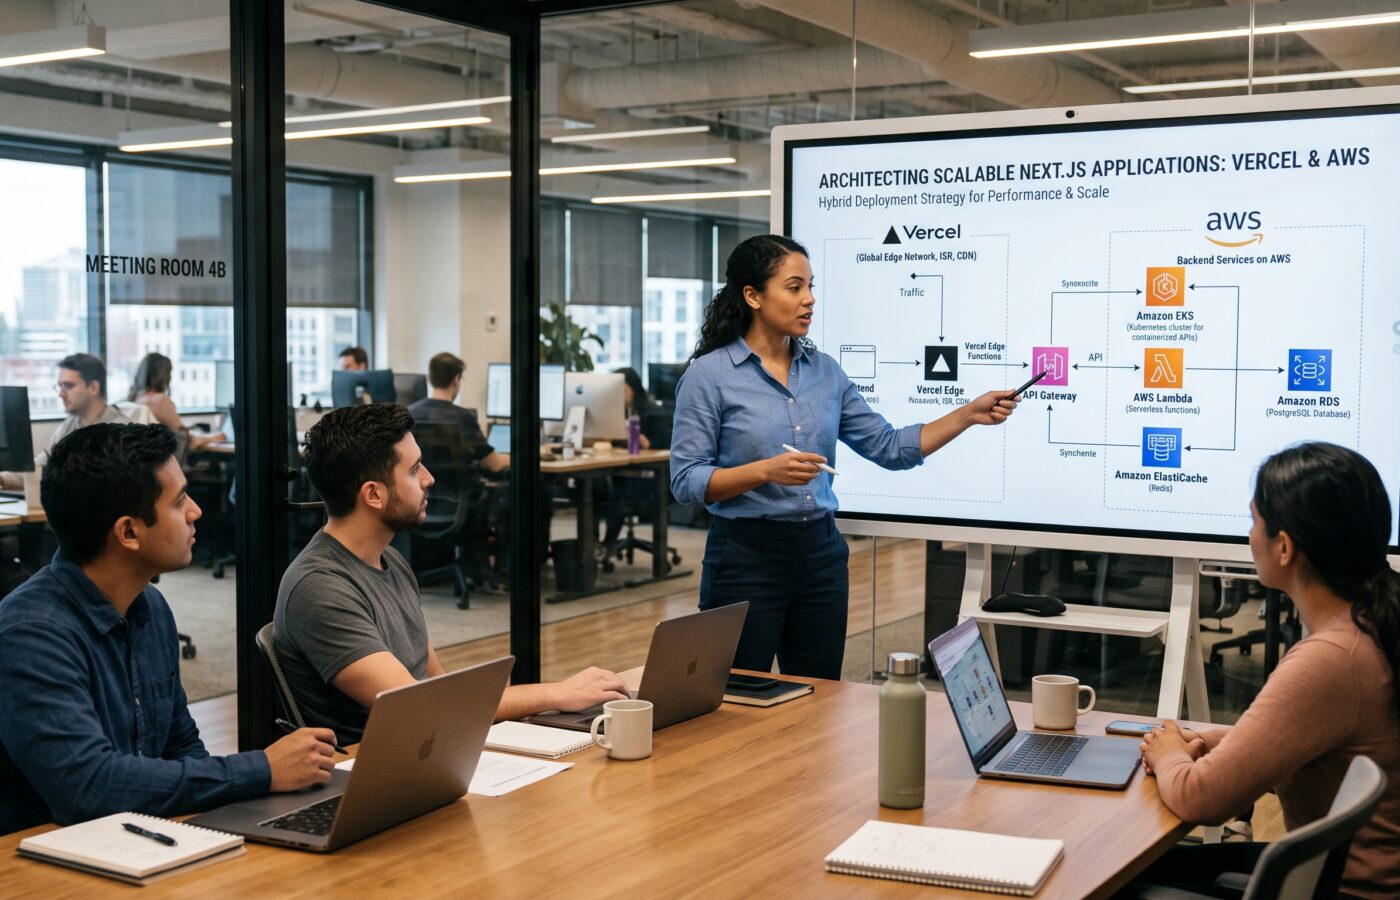
Vercel excels at the part of the stack it was built to handle: serving the Next.js app itself, edge routing, image optimization, and preview deployments for every pull request. AWS covers the parts that were never Vercel’s job: relational databases, message queues, background workers, long running jobs, and anything that needs to sit inside a private network for compliance reasons.
When I explain this to a CTO, I put it simply. Let the frontend platform excel at fronting. Let the cloud platform excel at everything with state and infrastructure weight. Forcing one tool to do both jobs is what hurts teams.
3. How do you decide between server rendering, static generation, and incremental static regeneration for a large application?
Marcus: This is the question I get asked the most. The honest answer is that most enterprise apps use all three at once, just on different routes. Marketing pages, documentation, and anything that doesn’t change per request should be static. There’s no reason to spin up compute for a page that looked the same yesterday.
Product catalogs, pricing pages, and content that updates on a schedule fit incremental regeneration well. You get static speed with content freshness measured in minutes instead of a full rebuild. Then you have the genuinely dynamic surfaces: account dashboards, checkout flows, anything personalized per user. Those need real server rendering or client side fetching behind authentication.
The mistake I see constantly is teams picking one strategy and applying it everywhere because it’s easier to reason about. It stays easier right up until build times balloon or dynamic pages feel sluggish because someone forced them into a static mold.
4. What about companies that need multi region deployment or have data residency requirements?
Marcus: This is where the AWS side of the house really earns its keep. Vercel’s edge network is genuinely fast and automatically handles a lot of the geographic distribution, serving cached content from a location near the visitor. But data residency isn’t about where a cached page lives. It’s about where you actually process and store the data.
If a customer needs European data to stay in Europe, that’s an AWS region and networking decision, not a frontend hosting decision. I typically architect it so the Next.js layer on Vercel routes requests intelligently, while backend services and databases sit in region specific AWS accounts with clear boundaries between them.
It takes more planning upfront, and you need someone who understands both platforms’ networking models. But it means you won’t end up explaining to an auditor why customer data crossed a border it wasn’t supposed to.
5. Walk us through what a mature CI/CD pipeline looks like for a Next.js app at this scale.
Marcus: It starts before code even reaches a shared branch. Every pull request should get its own preview deployment automatically. Vercel gives you that almost for free, and it’s one of the most underrated productivity gains I’ve seen in a decade of doing this work. A designer or product manager can click into a real, running version of the change instead of reading a diff.
From there, the pipeline needs automated testing gates, type checking, linting, and at least a smoke test suite that hits the critical user paths before anything touches a shared environment. On the AWS side, infrastructure changes run through their own pipeline entirely, usually infrastructure as code with a plan and approve step. You never want a database migration sneaking in alongside a UI tweak.
Staging should mirror production closely enough that surprises stay rare. Rollback needs to be a button, not a process someone has to remember at 3am. If your team can’t safely deploy on a Friday afternoon, your pipeline isn’t done yet.
6. How do you handle caching without it becoming a source of confusing bugs?
Marcus: Caching is where good architectures quietly go bad if nobody owns the strategy. You’ve got the browser cache, the CDN cache at the edge, Next.js’s own data cache and full route cache, and often something like Redis sitting in front of your database. Each layer has a different lifespan and a different invalidation trigger.
If two engineers carry different mental models of how those layers interact, you get the classic symptom: someone updated the content, but the page still shows the old version. My rule of thumb is simple. Document, in plain language, exactly what gets cached, for how long, and what clears it.
I also push teams toward time based revalidation over manual cache busting wherever possible. Manual invalidation is a promise that someone will remember to call it, and eventually someone won’t.
7. If Vercel is hosting the frontend, what exactly is AWS doing day to day?
Marcus: A lot more than people expect. Object storage through S3 handles user uploads and generated assets. Relational data lives in RDS or Aurora for anything transactional. Lambda or containers running on Fargate handle background processing, work that shouldn’t block a page render, like sending emails, generating reports, or processing webhooks.
SQS queues absorb spikes in demand so they don’t take down downstream systems. Secrets management, VPC networking for anything that needs to stay off the public internet, and often a good chunk of the authentication and authorization logic round out the picture. The Next.js app on Vercel usually calls into an API layer that lives in AWS, sometimes through API Gateway, sometimes through a service mesh, depending on how many internal services are involved.
The storefront analogy
None of that is visible to an end user, but it’s most of the actual engineering. Think of the Next.js layer as the storefront. Customers see it, and it needs to feel instant and polished. AWS is everything behind the counter: inventory, payment processing, staff scheduling.
A beautiful storefront with nothing organized behind it falls apart the moment real volume shows up. I’ve reviewed architectures where a team invested enormously in the frontend experience and treated the backend as an afterthought. It always surfaces eventually as latency, inconsistent data, or an outage the frontend had no way to prevent.
8. Let’s talk about security and compliance. What changes at enterprise scale?
Marcus: The stakes go up, and so does the paperwork, frankly. You’re no longer just protecting against generic attacks. You’re often proving to an auditor that specific controls exist and actually work, not just that they theoretically could.
On the Vercel side, we scope environment variables and secrets correctly per environment, so a staging key can never leak into production. On the AWS side, IAM roles follow least privilege religiously. Every service gets exactly the permissions it needs and nothing more, and we lock down network access with security groups and private subnets rather than relying on application level checks alone.
Single sign on becomes non negotiable past a certain headcount. Your audit logs need one place your security team can actually query, not a dozen scattered dashboards. I’ve seen teams treat compliance as a checkbox exercise at the end, and it always costs more that way than building it in from the start.
9. How do you monitor and debug an application that spans two platforms like this?
Marcus: You need a single pane of glass, or as close to one as you can get. Debugging across platform boundaries is genuinely harder than debugging a monolith. I typically wire up distributed tracing so I can follow a request from the edge, through the Next.js server functions, into whatever AWS service handles the backend logic, and back again.
Vercel’s own analytics and logging cover the frontend performance side well: real user metrics, function execution times, that sort of thing. CloudWatch, or a third party tool layered on top of it, covers the AWS side. The trick is correlating the two with shared request identifiers, so when something breaks you aren’t manually cross referencing timestamps across two dashboards at midnight.
You also need to tune alerting deliberately. Too many alerts and people start ignoring them. Too few, and you find out about outages from customers instead of your own systems.
10. Cost is always a concern once you’re operating at scale. How do you keep it under control?
Marcus: The biggest cost mistake I see is treating serverless functions as free just because they scale automatically. They scale automatically in cost too. I push teams to think about which routes genuinely need dynamic server rendering versus which ones could be static or cached. Every dynamic request on Vercel, and every corresponding backend call on AWS, carries a real dollar figure.
Reserved capacity and savings plans on the AWS side can meaningfully reduce costs for predictable workloads, while spiky or unpredictable traffic often costs less left on demand. I also recommend regular cost reviews, not just when a bill arrives higher than expected.
Set a baseline, watch the trend, and investigate anomalies immediately rather than at the end of the quarter. A single misconfigured function running in a loop can turn into an uncomfortable invoice surprisingly fast.
11. What’s the most common architectural mistake you see teams make with Next.js at this scale?
Marcus: Treating the migration to Next.js as purely a frontend project. It never is once you’re operating at any real scale. The frontend team gets excited about server components and rendering strategies, and meanwhile nobody has revisited how the API layer, the database, or the authentication system needs to change to support the new architecture.
I’ve walked into projects where a team had built a beautiful Next.js app that still made the same chatty, inefficient calls to backend services as the old application, just hidden behind a nicer interface. The framework can’t fix an architecture problem underneath it.
The second most common mistake is skipping the boring infrastructure work: proper environments, proper CI/CD, proper monitoring, because it feels less exciting than shipping features. Teams that skip it always pay for it later, usually during an incident, which is the worst possible time to build your first real deployment pipeline.
12. Last question. What advice would you give a team about to start this journey?
Marcus: Map out your rendering strategy and your data flow before you write a lot of code, not after. It’s one of those decisions that’s cheap to change on a whiteboard and expensive to change once 12 different routes already lean on assumptions that turned out wrong. Bring your platform and security people in from day one rather than looping them in right before launch.
Resist the urge to over engineer for scale you don’t have yet. I’d rather see a team ship a slightly simpler architecture they fully understand than a sophisticated one nobody can operate confidently at 2am. You can always add complexity later when traffic and requirements actually demand it. Adding it preemptively just gives you more surface area to debug for a problem you might never face.
Make time to actually learn the platforms
One last thing I’ll add, because people rarely ask about it directly. Budget time for your team to learn the platforms, not just ship on them. I’ve watched talented engineers spend weeks fighting a deployment issue that the documentation already covered, simply because nobody had made time to read it properly before launch started breathing down their neck.
A few days of deliberate learning early on saves weeks of guesswork later. That applies equally to Next.js itself, to Vercel’s platform behavior, and to whichever corner of AWS your backend leans on most heavily.
The takeaway
That’s where we left the conversation, though Marcus made a point of saying none of this is a fixed recipe. He adjusts every one of the 12 answers above depending on the industry, the infrastructure a company already has, and how much risk tolerance leadership carries once real customer data is on the line.
What stayed consistent across every project he described was the underlying philosophy. Let Vercel do what it’s genuinely best at. Let AWS do what it’s genuinely best at. Spend the real engineering effort on the seams where the two meet, because that’s where most of the expensive mistakes tend to hide.
Frequently Asked Questions
Is Vercel or AWS better for hosting a Next.js application?
Neither one wins outright, they solve different problems. Vercel focuses specifically on Next.js deployment, preview environments, and edge delivery, while AWS provides the broader infrastructure, databases, and compute that most applications also need. Many enterprise teams run both together rather than choosing one exclusively. u11d has a detailed comparison of the two approaches.
Can Next.js run entirely on AWS without Vercel?
Yes. You can deploy Next.js on AWS using services like Lambda, Fargate, or Amplify, though it typically takes more manual configuration to replicate features Vercel provides out of the box. This walkthrough from DEV Community covers several available approaches.
What is the difference between ISR and SSR in Next.js?
Server side rendering generates a page on every request. Incremental static regeneration serves a cached static page and refreshes it in the background on a set interval. ISR generally costs less and runs faster for content that doesn’t need to be unique per request. LogRocket breaks down how these strategies interact with caching.
How do enterprises handle authentication across Vercel and AWS?
Authentication logic commonly lives closer to the backend services in AWS, often using Cognito or a third party identity provider, while the Next.js frontend on Vercel handles session tokens and route protection. This setup keeps sensitive identity logic inside the more controlled AWS network boundary.
Is Next.js suitable for large enterprise applications?
Yes, though it demands the same architectural discipline any large application needs regardless of framework: a clear rendering strategy per route, proper caching layers, dedicated CI/CD pipelines, and a well planned backend. freeCodeCamp offers solid technical grounding in the caching and rendering model behind these decisions.
How can teams reduce hosting costs when scaling Next.js?
Favor static generation and ISR over server rendering wherever the content allows it. Monitor function execution costs regularly rather than only at billing time, and use reserved AWS capacity for predictable workloads. Schedule cost reviews instead of waiting for a surprising bill.
References
- Life of a Vercel request: Navigating the Edge Network (Vercel)
- Maximize Uptime with Vercel’s Frontend Cloud (Vercel)
- Vercel: Global network and regions (Vercel)
- Advanced Next.js caching strategies (LogRocket)
- 8 reasons your Next.js app is slow and how to fix them (LogRocket)
- Learn Next.js 15 Caching and Rendering (freeCodeCamp)
- AWS Amplify vs Vercel: Complete Pricing Comparison for Next.js Applications (u11d)
- Next.js deployment on AWS Lambda, ECS, Amplify, and Vercel: what I learned (DEV Community)
- Serverless Containers with Next.js, AWS Fargate, and AWS Amplify (DEV Community)