Almost every company that hires me for DevOps services opens with the same question: “What are we actually paying for, and how will we know it worked?” Usually a CFO or COO asks it. Other times, it’s a VP of Engineering who has to defend a budget line he only half understands.
To be fair, it’s a reasonable question. I’ve spent close to two decades building delivery pipelines, migrating workloads, and sitting in war rooms at two in the morning. During that time, I’ve seen DevOps services transform companies. At the same time, I’ve also seen them burn six figures on tooling nobody used. In most cases, the difference was not the technology. Instead, it was whether anyone defined the scope clearly and agreed up front on how value would be measured.
For that reason, this piece covers both. First, what a real DevOps services engagement includes, beyond the vendor slide deck. Second, a practical way to measure the return so that it holds up in a budget review.
Why DevOps Services Are So Hard to Buy
Originally, DevOps started as a cultural movement, not a product. In other words, it was about developers and operations people sharing responsibility for software running in production. Since then, however, the industry has turned it into job titles, certifications, and a marketplace of tools. As a result, the word now means something slightly different to everyone.
For example, when a company says it wants to hire DevOps services, it might mean any of these:
- “Our releases are painful and we want them automated.”
- “We’re moving to the cloud and need help.”
- “Our site keeps going down and we don’t know why.”
- “Our cloud bill doubled and nobody can explain it.”
- “We need SOC 2 or ISO 27001 and our infrastructure is a mess.”
Clearly, each of those is a legitimate need. Even so, each one calls for a different mix of work. Therefore, a good provider separates them before quoting anything. A poor one, by contrast, sells the same package to everybody.
What DevOps Services Actually Include
Below is how I break down a full scope of DevOps services when I write a statement of work. Of course, not every company needs every piece. Still, you should know they exist so that you can tell what’s missing from a proposal.
1. Assessment and Baseline: Where DevOps Services Begin
To begin with, every engagement I run starts with an assessment, usually two to four weeks. During this phase, we map how code moves from a developer’s laptop to production, who approves what, where work waits, and how incidents are handled.
Above all, the most important output is a baseline. After all, you can’t measure ROI without a “before” picture, and yet almost nobody has one. For instance, I’ve watched teams swear their lead time was “a day or two” when the data actually showed eleven days, most of it spent waiting for a manual QA sign off.
So if a provider wants to skip straight to building pipelines, push back. Without the baseline, every ROI claim afterward is simply guesswork.
2. CI/CD Pipeline Automation as Core DevOps Services
Typically, this is what most people picture when they think of DevOps services. Continuous integration means every code change is automatically built and tested. Similarly, continuous delivery means a change that passes those checks can reach production through an automated, repeatable path.
However, a real pipeline engagement covers more than installing Jenkins, GitHub Actions, or GitLab CI. In addition, it includes branching strategy, artifact management, automated test stages, security scanning, environment promotion rules, and deployment strategies like blue/green or canary releases. Ultimately, the goal is boring, predictable releases. In fact, if deploying on a Friday afternoon still makes your team nervous, the pipeline isn’t finished.
3. Infrastructure as Code
Put simply, infrastructure as code means your servers, networks, databases, and permissions are defined in version controlled files (Terraform, OpenTofu, Pulumi, CloudFormation) instead of clicked together in a console.
Interestingly, this is the part of DevOps services that executives undervalue most. Even so, it’s the part I’d fight hardest to keep in scope. Because infrastructure lives in code, you can rebuild an environment in an hour instead of a week. Likewise, you can review infrastructure changes the same way you review application code. Moreover, when an auditor asks who opened that firewall port and why, the answer sits right there in the commit history.
4. Cloud Architecture and Migration
In many cases, engagements include moving workloads to AWS, Azure, or Google Cloud, or making better use of the cloud a company already pays for. Specifically, this covers landing zone design, account structure, networking, identity, and decisions about containers, Kubernetes, serverless, or plain virtual machines.
Here is one opinion from experience: Kubernetes is not a default. In fact, I’ve talked more than one client out of it, because a managed container service or a few well run VMs met their needs at a fraction of the operational cost. Generally speaking, a provider who recommends the most complex option every time is usually optimizing for their billable hours.
5. Observability and Monitoring
Essentially, monitoring tells you when something is broken, whereas observability helps you understand why. Accordingly, this workstream covers metrics, logs, traces, dashboards, and alerting tied to real user impact rather than CPU graphs.
More importantly, the work that matters here is defining service level objectives. An SLO is a written promise, for example “99.9% of checkout requests succeed within 800 milliseconds over 30 days.” Once that exists, engineering and the business share one definition of “healthy.” Consequently, the question of whether to ship features or fix reliability becomes much easier to settle.
6. Incident Response and Site Reliability Practices
Furthermore, good DevOps services include the human side of operations: on call rotations that don’t burn people out, runbooks, escalation paths, and blameless postmortems. Additionally, some providers offer managed on call or a site reliability engineering function as an ongoing retainer.
Personally, I judge an organization’s maturity less by its uptime and more by what happens after an outage. For instance, does the team write up what happened, find the systemic cause, and fix it? Or, on the other hand, does someone get blamed while the same incident returns three months later?
7. DevSecOps and Compliance Automation
Equally important, security has to be built into the pipeline rather than bolted on before an audit. This includes dependency and container image scanning, secrets management, policy as code, least privilege access, and automated evidence collection for frameworks like SOC 2, HIPAA, or PCI DSS.
For regulated businesses in particular, this piece alone can justify the engagement. For example, I’ve seen compliance prep drop from a quarter long scramble to a few weeks, simply because the evidence was already generated by the pipeline.
8. Platform Engineering in Modern DevOps Services
Next comes the newer layer in DevOps services: the internal developer platform. In short, it’s a set of golden paths, templates, and self service tools that let product teams spin up a new service with logging, monitoring, and deployment already wired in.
Notably, this has become more important with AI coding assistants. According to the 2025 DORA research, AI adoption among software development professionals has climbed to 90%. At the same time, however, the same research points to software stability becoming a significant concern since generative AI took off. In plain terms, developers write code faster, but without strong platforms and guardrails, more of it breaks in production. Therefore, a good platform is how you capture the speed without the chaos.
9. FinOps and Cloud Cost Optimization
Today, cloud spend is a top three line item for many software businesses. As a result, DevOps services increasingly include tagging strategies, rightsizing, reserved capacity planning, autoscaling, and cost dashboards that show spend by team or product.
Often, this is the fastest visible win. In my experience, a first serious cloud cost review typically finds meaningful waste, such as idle environments, oversized databases, forgotten snapshots, and test clusters running all weekend.
10. Training, Documentation, and Handoff
Finally, the last component, and the one most often cut to save money, is knowledge transfer. If the provider builds everything and then walks away, you’ve bought a dependency rather than a capability. For this reason, the engagement should end with your team able to run, change, and extend what was built. In practice, I write handoff criteria into the contract: the client’s engineers perform the last several releases and also handle a simulated incident without us.
Engagement Models for DevOps Services: Project, Retainer, or Embedded
Broadly speaking, DevOps services are sold in one of three shapes.
Fixed scope projects suit clearly defined work such as a cloud migration or a pipeline build. On the plus side, they’re easy to budget for. On the downside, they can get rigid when requirements shift.
Managed services or retainers, on the other hand, suit companies without in house operations staff. In this model, the provider runs infrastructure, on call, and patching for a monthly fee. Even so, be clear about response times and exactly what “managed” covers.
Embedded or team augmentation places senior engineers inside your teams for months. Admittedly, it’s the most expensive per hour. Nevertheless, it’s usually the best at changing culture, because your people learn by working beside experienced practitioners.
In the end, there’s no universally right answer. After all, a 40 person SaaS company with two backend developers needs something very different from a bank with 600 engineers.
How to Measure the ROI of DevOps Services
Now for the part the CFO cares about. Mathematically, ROI uses the same arithmetic as any investment: total gains minus total costs, divided by total costs. The hard part, however, is deciding what counts as a gain and then getting honest numbers for each.
To do this, I use a four layer model. The bottom layers are easy to measure, yet they mean little to the business on their own. Meanwhile, the top layers matter most but need translation.
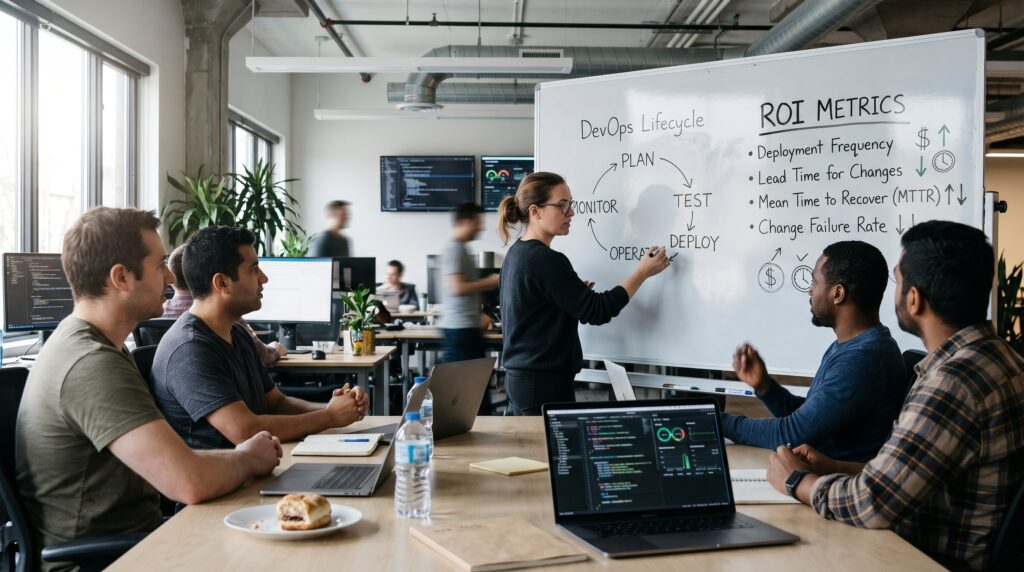
Layer 1: Delivery Performance (the DORA Metrics)
For more than a decade, the DevOps Research and Assessment program, now part of Google Cloud, has studied software delivery. Specifically, DORA defines four key metrics, grouped into throughput and stability.
- Deployment frequency: how often you release to production.
- Change lead time: time from a code commit to running in production.
- Change failure rate: the share of deployments that cause an incident, rollback, or hotfix.
- Failed deployment recovery time: how long it takes to recover when a release goes wrong.
Importantly, there’s one finding I repeat to every skeptical executive: these four tend to move together. In other words, top performers do well across all of them, while low performers do poorly. Speed and stability, therefore, are not a tradeoff when the engineering is done properly. For reference, DORA’s research places high performing teams at a change failure rate between 0 and 15%.
That said, DORA’s own guidance includes a warning. Turning these metrics into targets, or using them to single out teams, tends to create friction and blame. So use them to diagnose rather than to punish. Otherwise, the moment deployment counts become a performance review metric, people start splitting changes into meaningless pieces to inflate them.
Layer 2: Operational Cost Savings from DevOps Services
At this layer, real dollars start to show up. Accordingly, track the following:
- Engineering hours spent on manual work: releases, environment setup, patching, and firefighting. To get this, survey your team before and after, or pull data from tickets and time tracking.
- Cloud and infrastructure spend: normalized against usage, for example cost per thousand transactions or cost per active customer. Since raw spend can rise as the business grows, normalization keeps the comparison fair.
- Tool consolidation: licenses retired because the new platform replaced them.
- Unplanned work ratio: the share of engineering time going to incidents and rework instead of planned features.
Then convert hours to dollars using a fully loaded cost per engineer. In other words, include salary plus benefits, overhead, and equipment, not salary alone.
Layer 3: Reliability Gains from DevOps Services
Frequently, downtime is where DevOps services earn back their entire cost in one quarter. Indeed, the numbers are large. For example, ITIC’s 2024 survey of more than 1,000 firms found that over 90% of midsize and large enterprises put the cost of a single hour of downtime above $300,000. Similarly, New Relic’s 2025 Observability Forecast reported a median cost of $2 million per hour for high impact outages.
However, don’t use industry averages in your own business case. Instead, build your own number. A practical formula adds up lost revenue, idle staff cost, recovery and incident labor, and SLA penalties. Next, multiply that hourly figure by the hours of downtime avoided compared with your baseline year. As a result, you’ll have a defensible reliability gain.
In addition, include these:
- Security incidents prevented or contained faster: vulnerabilities caught in the pipeline rather than in production. (Pipeline scanning complements, but doesn’t replace, periodic penetration testing.)
- Audit and compliance effort: hours saved preparing evidence, plus any reduced audit fees.
- Recovery capability: how quickly you could rebuild an environment after a disaster. Admittedly, it’s hard to price until the day you need it.
Layer 4: Business Outcomes
Lastly, this is the top layer and the hardest to attribute. Even so, it’s also where the biggest returns usually sit.
- Time to market: if features ship weeks earlier, what is that worth in revenue, contract wins, or competitive position?
- Experimentation rate: how many product experiments or A/B tests the team can run per quarter.
- Customer impact: churn, conversion rates, and support tickets tied to bugs or outages.
- Talent retention: engineers rarely leave teams where releases are calm and on call is sane. Moreover, replacing a senior engineer can cost a large share of their annual salary once you count recruiting, ramp up, and lost productivity.
Above all, be conservative here. Typically, I count only the business outcomes that the client’s own product or finance leaders agree to sign off on. After all, one credible number beats five optimistic ones.
Mistakes That Wreck DevOps Services ROI Calculations
Over the years, I’ve reviewed plenty of DevOps business cases that fell apart under scrutiny. Not surprisingly, the same errors appear again and again.
Counting only vendor fees as the cost. In reality, your engineers spend real time in workshops, reviews, and migration work. Jellyfish makes this point well: most DevOps ROI reports overstate returns by ignoring internal labor costs, while also understating them by leaving out revenue impact. Unfortunately, both errors are common, and they don’t cancel out.
No baseline. As mentioned above, this is the number one failure. Simply put, if you can’t show where you started, nobody will believe where you ended up.
Measuring too early. Usually, months one through three look worse. That’s because teams are learning new tools, running old and new processes in parallel, and fixing problems the assessment uncovered. Real returns, by contrast, typically show between months six and eighteen. So set that expectation in writing before kickoff.
Attributing everything to DevOps. For example, if revenue grew 30% the same year you modernized the pipeline, DevOps didn’t cause all of it. Consequently, overclaiming destroys credibility with finance teams fast.
Ignoring the cost of doing nothing. Sometimes, the honest ROI case is defensive. For instance, legacy infrastructure, unpatched systems, and the one engineer who knows how deployments work are all liabilities with a price tag, even if it hasn’t been invoiced yet.
A Worked Example of DevOps Services ROI
To make this concrete, here’s a simplified version of a case I built for a midsize B2B software company. Although the figures are rounded and anonymized, the structure is real.
Investment over 12 months: $420,000 in external DevOps services plus roughly $110,000 of internal engineering time, for a total of $530,000.
Measured gains over the same 12 months:
- First, manual release and environment work dropped by about 2,600 engineering hours. At a fully loaded $95 per hour, that’s roughly $247,000.
- Second, cloud spend per active customer fell 22%, which was worth about $180,000 annualized.
- Third, major incidents fell from nine to three. Using the client’s own downtime cost model of around $40,000 per incident, that equals $240,000 in avoided losses.
- Finally, SOC 2 evidence collection was automated, thereby saving about $60,000 in consultant fees and staff time.
Total measured gain: about $727,000. Therefore, ROI equals ($727,000 minus $530,000) divided by $530,000, or roughly 37% in year one.
Notice, however, what isn’t counted. The client also shipped a major product release about seven weeks ahead of the prior year’s pace and, as a result, signed two enterprise contracts that depended on it. Nevertheless, we left that out of the core figure because attribution was arguable, and instead noted it as upside. Meanwhile, year two ROI was considerably higher, because the build cost was mostly behind them while the savings kept recurring.
By comparison, vendor commissioned studies often report bigger numbers. Forrester’s Total Economic Impact studies, for example, interview a handful of customers to produce a framework for estimating the financial impact of a given DevOps approach. They’re useful for structure. Even so, treat their headline figures as illustrations rather than forecasts for your business.
How to Evaluate a DevOps Services Provider
Before signing anything, I’d ask any provider these questions:
- How will you establish our baseline metrics, and will we own that data?
- Which outcomes will you commit to, and how exactly will they be measured?
- What does the handoff look like, and how do you know our team can run this without you?
- Can we speak with a client 12 months past the engagement, rather than one still in it?
- When have you recommended against a more complex architecture?
Of all of them, the last question tells you the most. Experienced architects, after all, have strong opinions about what not to build. So if every answer involves more tools, more clusters, and more managed services, keep looking.
Final Thoughts on DevOps Services
In the end, DevOps services are not a magic subscription that makes software faster. Rather, they’re a set of engineering practices, automation, and operating habits that compound when they’re done well. Thus, the companies that get a strong return treat the engagement like any other capital investment. In other words, they define scope, record a baseline, agree on the metrics, and then review results honestly every quarter.
So if you take one thing from this article, make it this: measure before you build. Otherwise, everything else, from the pipeline to the platform to the ROI slide in next year’s budget review, rests on a guess about where you started.
Frequently Asked Questions
What do DevOps services typically include?
Generally, a complete engagement covers assessment and baselining, CI/CD pipeline automation, infrastructure as code, cloud architecture, observability, incident response practices, security and compliance automation, platform engineering, cloud cost optimization, and knowledge transfer. For an overview of the core practices, see the Atlassian DevOps guide.
How long before DevOps services show a return?
Typically, organizations see early wins such as faster releases or lower cloud spend within three to six months. Meaningful financial return, however, usually arrives between six and eighteen months. In addition, Spacelift’s guide to DevOps ROI explains why ROI is rarely a single calculation and how to track it over time.
What are the DORA metrics and why do they matter for ROI?
Specifically, they are deployment frequency, change lead time, change failure rate, and failed deployment recovery time. Because they measure delivery speed and stability, they serve as leading indicators for cost and reliability gains. For the official definitions, see DORA’s guide to the four keys.
How does downtime cost factor into DevOps services ROI?
To start, add lost revenue per hour, idle staff cost, incident and recovery labor, and any SLA penalties, then multiply by the downtime hours avoided. Furthermore, ManageEngine’s breakdown of hourly downtime costs walks through the formula with benchmarks by company size.
Does AI change what DevOps services should include?
Yes. Since AI coding tools increase the volume of code changes, they put more pressure on testing, review, and platform guardrails. Moreover, InfoQ’s coverage of the 2025 DORA report explains why AI tends to amplify a team’s existing strengths and weaknesses.
Should we hire an in house DevOps team or use external DevOps services?
Ultimately, it depends on size and maturity. Smaller companies often get better value from a managed or project based provider, whereas larger engineering organizations usually build internal platform teams with outside help for specific initiatives. Likewise, Datamation’s article on the ROI of DevOps covers how staffing efficiency factors into that decision.
References
- Harvey, N. DORA’s Software Delivery Metrics: The Four Keys. DORA.
- InfoQ. DORA Report Finds AI Is an Amplifier in Software Development, But Trust Remains Low. September 2025.
- TechRepublic. Google DORA Research: Software Developers Use AI Heavily. September 2025.
- Codefresh. DORA Metrics: 4 Key Metrics for Improving DevOps Performance.
- Quash. Downtime Cost Statistics 2026: What an Hour of Outage Costs.
- ManageEngine. How Much Does an Hour of Network Downtime Cost?
- Jellyfish. How to Measure DevOps ROI: Methods, Metrics and Best Practices.
- Spacelift. DevOps ROI: Why It Matters and How to Measure.
- Atlassian. The Total Economic Impact of Atlassian Open DevOps, Forrester Study.
- Irani, Z. The ROI of DevOps: 5 Key Metrics. Datamation.